

Reading a job match score:
when to trust it, when to override it
11 Minutes read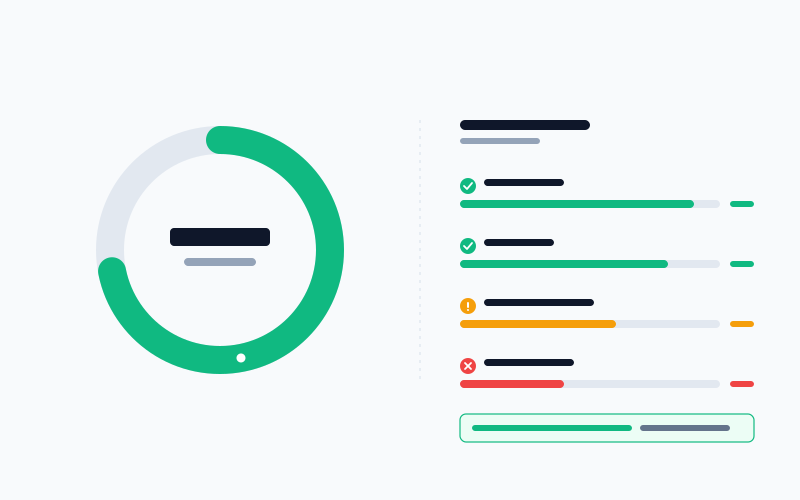
Every modern job tool puts a percentage next to a role. That number is useful only if you understand what it is, and what it isn't.
Open any modern job-search product and a number will be attached to each role. 87%. 62%. 34%. The number is a triage tool, and for most candidates it's the single most-referenced piece of UI during an active search.
It's also the most commonly misread. "87% match" does not mean "87% chance of getting this job." It does not mean "87% cultural fit." It means something much narrower, and the gap between what it means and what candidates assume it means is where the bad applications get sent.
This post is a guide to reading any match score, AI-driven or rule-based, with the right mental model. What the number is actually saying, what it isn't, and when your own judgment should override it. Further down there's a section on how the one in Jobiz works.
What the score is genuinely measuring
Strip away the marketing. Every match score is, under the hood, doing roughly the same thing: comparing what the job posting says it wants against what your resume and stated preferences say you offer, and producing an aggregate confidence.
The comparison has three or four components (the specifics vary by product) but they cluster around the same categories:
- Do the skills and tools overlap? If the posting wants Kubernetes and your resume has never touched a container, the score drops.
- Is this at your level? A staff engineer gets a low slice here on an entry-level posting. A mid-level gets a low slice on a staff+ role.
- Do the actual responsibilities match? Two roles with the same title can be completely different jobs. Whether your past work pattern-matches against this role's responsibilities is what this component is checking.
- Do the logistics work? Location, remote/hybrid/on-site, comp range, timezone. Any of these being a hard no from your side caps the score regardless of the rest.
The final score is a weighted combination of those components. Different products weigh them differently; some apply caps or penalties for specific mismatches. The common denominator: the number is an aggregate summary of "how closely does what this role wants line up with what you have and want."
What the score is not doing
Three things the number is often assumed to be, but is not:
It is not a hire-probability. Nobody has a model that predicts whether a specific posting will lead to an offer for you. The variables that would actually predict that (competing candidates, hiring manager's week, comp band, internal politics, your references, whether the recruiter is hungry when they read your resume) are not visible from a resume + JD. Any number that claims to predict offers is either using proxies that don't generalize, or is wishful thinking.
It is not an interview-probability either. That's a weaker claim and still almost nobody has it. Whether you get the interview depends on the recruiter's workload, the size of the applicant pool, whether you're applying cold or through a referral, and a dozen other things the scoring model cannot see.
It is not a measure of interpersonal fit. "Will you enjoy working with these people" is a conversation, not a score. Anyone selling a "culture fit score" based on a JD and resume is selling you something the data cannot support.
What the score does measure well is the overlap between stated inputs. That's a useful thing to measure. It is not the same thing as a prediction.
How the score in Jobiz works
Many products hand each posting and your resume to a language model and ask it for a number. Jobiz doesn't. Your resume is read once, when it changes, into a matching profile: what you've done, what you know, how long you've done it, what you studied, the languages you work in. Every posting is read the same way. The score is the two set side by side, and it's computed on our servers for the jobs on your screen.
That has three practical consequences:
- The same resume and the same posting always give the same number. No drift between Monday and Tuesday, no score that changes because a model phrased its answer differently.
- It's free. Every job in Find jobs and the Tracker gets a score on every plan, not just the ones you pick.
- It's always current. Edit your resume and the scores follow it. There's nothing to re-run.
It reads across languages: a resume written in Italian matches a posting written in English or German. And it reads what each posting really asks for, so the experience, skills and qualifications the role treats as essential matter more than the ones it would merely like.
Next to every score you see why: what you have that the role asks for, what's missing, and what to check, such as a licence, a language level or who may apply. That list is the part to act on.
What it deliberately leaves out: salary, company, team, and anything else the posting can't state as a requirement. Those are yours to weigh, which is the subject of the rest of this post.
The three cases where the score is genuinely useful
Given all the caveats, there are three specific uses for a match score where it produces real value, and essentially only these three.
1. Triage
This is the big one. When you open a search result and see twenty postings, the score tells you which three to read carefully and which seventeen to skim. It's a sorting mechanism, not a verdict. Roles scored 75+ deserve a close read; roles scored below 35 almost never do; the middle band is judgment.
Triage is where the time savings live. A well-calibrated score can turn 30 minutes of reading JDs into 10 minutes of targeted review.
2. Understanding why a role scored the way it did
The aggregate number is less useful than the reasoning behind it. A 72% that lands because of a skills overlap but a level mismatch tells a different story than a 72% that lands because of a softer match across every dimension. The first is a level mismatch (maybe worth a stretch application with a strong cover letter). The second is a broader soft-match (probably worth reading but not a top-tier target).
Products that show only the aggregate number and not any explanation of the components are less useful than products that surface the reasoning, whether through per-component sub-scores or a written breakdown. If you have a breakdown available, read it before deciding how to apply.
3. Seeing patterns across many postings
If every role in your target category is scoring in the 40s, the score isn't the problem: your preferences or your resume are producing the pattern. Either your target is too narrow, your resume is too thin for the level you want, or your preferences don't match the market.
This is a meta-use that requires volume: individual scores are noisy, but patterns across thirty or forty postings reveal whether something upstream is broken.
When to override the score
Four cases where the score should be ignored:
High score but the company is on your no-list. The model doesn't know you interviewed there in 2022 and hated it, or that a friend told you the team is miserable, or that their product competes with your current employer. The score can't see those inputs; your history can.
Moderate score but the hiring manager is someone you've worked with. Warm-intro roles are high-conversion regardless of how well the posting's keywords match your resume. A score of 62% via a warm intro beats an 87% via cold application roughly every time.
High score for a role at a direct competitor. Legal factors (non-competes, non-solicitation clauses, client relationships) aren't in the score. These are judgment calls that dominate the numeric signal.
Low score for a deliberate stretch. If you're actively trying to break into a new level or function, your resume is going to lag behind what the target roles want. The score will mark those as mismatches. Some of them still deserve serious applications, but choose them selectively, and accept that the conversion rate will be lower.
How much precision is too much
There's a failure mode where candidates spend real time arguing with the score. "Why is this 72% and not 78%?" is usually the wrong question. The score is a rough calibration, not a laboratory measurement. A 5-point difference often reflects noise in how one word was parsed, or whether a specific skill was mentioned twice on your resume instead of once.
The useful mental model is: treat scores in buckets rather than as precise numbers. Above 75 is "very close match." 55–75 is "reasonable match, read carefully." 35–55 is "possible match, needs a judgment call." Below 35 is "probably mis-targeted." That's all the precision the underlying signal actually supports.
Fighting for the fifth percentage point is wasted cognition.
The confidence-band problem
A 72% is not always a 72%. The confidence of the scoring model varies based on how specific the inputs are.
- If your resume is detailed (specific projects, quantified outcomes, named tools) and the JD is detailed (specific responsibilities, clear requirements, named technologies), the model has enough signal to produce a high-confidence score. That 72% is probably close to right.
- If either side is thin (a vague JD, a generic resume) the model is guessing, and the 72% could be 55% or 85% with equal plausibility.
Products that show confidence alongside the score are more useful than ones that don't. If yours doesn't surface confidence explicitly, a rough heuristic: low-confidence scores correlate with thin resumes or vague JDs. If you notice your scores bouncing around unpredictably, the underlying inputs are probably the cause.
In Jobiz this is built into the skills part: a skill your resume demonstrates (in a bullet, with what you did) counts for more than the same skill sitting in a skills list. A thin resume doesn't get the benefit of the doubt.
Addressing this is upstream of the score: a more specific resume produces more reliable scores, which produces better triage, which produces better application choices. The resume's quality compounds.
The part nobody talks about
Modern match scoring is strictly better than the raw keyword matching of a decade ago. Keyword matching missed variants constantly: "k8s" vs "Kubernetes", "React.js" vs "React", a skill listed under a slightly different name. Modern scoring handles that reliably, whether through a model reading both texts or through a shared skill vocabulary that maps the variants to one skill.
But strictly better than bad is not the same as actually good. The scoring model still cannot see inside the hiring team. It cannot predict timing. It cannot quantify your unique wedge: the specific reason a hiring manager might remember your application above the others. Those are the parts that actually decide hires, and they're invisible to any score.
Use the score as a first-pass filter. Don't use it as an oracle. Used that way, it saves real hours. Used as an oracle, it produces worse decisions than reading the JD yourself would have.
The meta-takeaway
Every job-search product in 2026 will show you a number next to each role. The numbers differ between products, the weighting schemes differ, the confidence bands differ, but the underlying shape is the same: a compressed summary of skill-scope-responsibility-logistics alignment.
Treat all of them the same way. As a triage signal, not a verdict. As a starting point for your judgment, not a replacement for it. As most useful when you read the breakdown rather than just the aggregate. As least useful when you argue with the fifth percentage point.
Candidates who internalize that mental model save hours a week during an active search. Candidates who treat the number as predictive of outcomes end up disappointed in both directions: applying confidently to roles that were never a real fit, and ignoring roles that would have been.
The score is a tool. Treat it like one.
Every match score in Jobiz comes with a breakdown in the job's Match tab: a one-line verdict (Strong match at 75 and above, Good fit from 55, Partial fit from 35, Weak fit below), whether the role is in your field, the posting's skills grouped by importance with the ones you have and the ones you lack, and checks on years, education, and languages. Not just the top-line percentage. The reasoning is usually where the actually-useful information lives, and since the score runs in your browser, reading it is free on every plan.
No spam. Unsubscribe anytime.
Related Articles
Cover letters across languages: the parts that don't translate
A cover letter in German isn't an English one run through a translator. The parts that matter most are conventions, not sentences.
 Jobiz Team
The case against browsing for jobs
Opening LinkedIn five times a day feels like job-searching. It mostly isn't. Here's why scheduled-delivery habits beat browsing-based ones.
Jobiz Team